How to Audit 1,000 Articles Without Treating Every Page the Same
TLDR
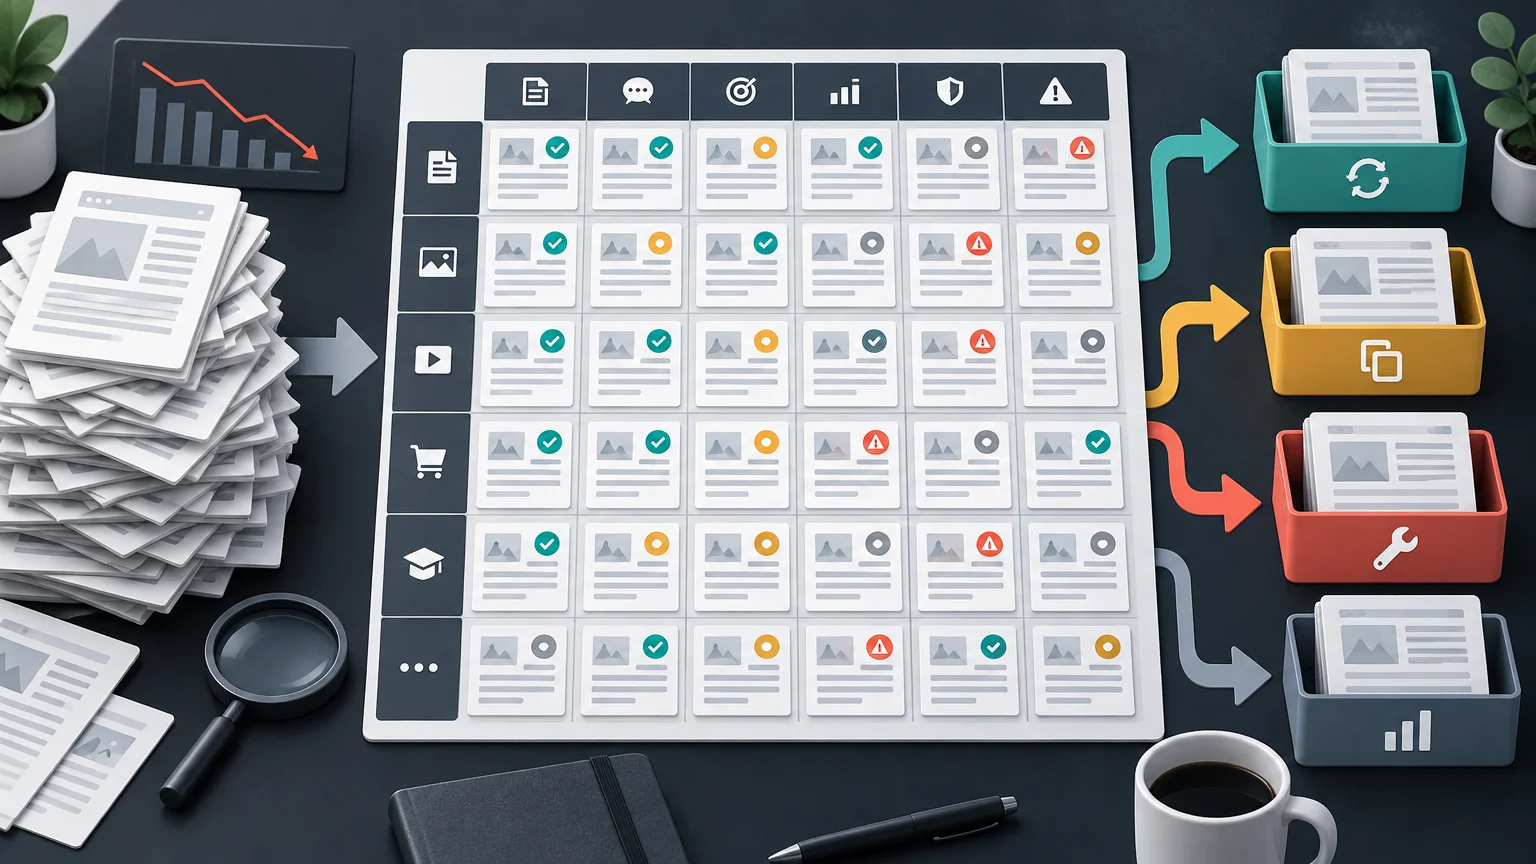
Large site content audit segmentation should happen before pages are scored or assigned actions. Group URLs by page type, reader job, topic, organic performance, business value, authority, freshness and technical state. Then compare pages only within sensible cohorts. A low-traffic support article, discontinued product page and indexable filter URL may all look weak in a spreadsheet, but they require different decisions.
The fastest way to ruin an audit of 1,000 articles is to give every URL the same test. Traffic thresholds, word counts and publication dates are convenient filters, not reliable verdicts. A useful audit identifies what each page is supposed to accomplish, examines evidence relevant to that purpose and sends the URL to a defensible action queue.
Why traffic-only audits produce bad decisions
Traffic is an observation, not a diagnosis. Low organic traffic can indicate weak demand, poor rankings, an indexing problem, seasonality, a narrow but valuable audience or a page that was never intended to attract search visits. High traffic can disguise factual decay, poor conversions, intent mismatch or substantial overlap with another URL.
Consider four URLs showing fewer than 20 organic clicks in a month: a product page that generated two sales, a regulatory guide between seasonal peaks, an orphaned tag archive and a noncanonical parameter URL. Grouping all four under “underperforming content” hides the actual work. The product may deserve protection, the guide may need monitoring, the archive may need retirement and the parameter URL belongs in technical triage.
Google’s people-first guidance asks whether content provides original information, substantial value relative to other results, a clear purpose and a satisfying experience. It also cautions against changing dates merely to make pages appear fresh when their content has not substantially changed. Those are better editorial questions than “Is this page over 1,000 words?” Google’s people-first content guidance
Build a minimum viable URL inventory
A crawl export is not yet a content audit. It tells you what a crawler encountered, but not necessarily what a page is for, whether it generates value or how the business should handle it. Combine crawl data with CMS records, sitemap inventory, Search Console, analytics, conversion data, link data and editorial metadata. No individual source describes purpose, search performance, authority, business value and indexation state completely.
At minimum, create fields for:
- URL, title and page type or template
- HTTP status, indexability, canonical target and robots directives
- Organic clicks, impressions, click-through rate and trend over comparable periods
- Primary query class, search intent and reader job
- Publication date and date of the last material update
- Topic cluster, content owner and intended audience
- Conversions, revenue, leads, assisted value or support value where available
- Referring domains, important backlinks and internal-link count
- Editorial differentiation, factual-expiry and compliance risks
- Proposed action, evidence behind it and review owner
Search Console page and query data can help identify visibility patterns, but it needs careful interpretation. Some queries are anonymized or omitted, so the query table does not represent every search. Performance is also generally assigned to canonical URLs, which can make a noncanonical duplicate appear to have no visibility of its own. Search Console’s explanation of performance dimensions is useful context for anyone building the export.
For very large inventories, separate sitemaps can provide another segmentation and monitoring layer. Google supports sitemap indexes and multiple sitemaps, while recommending that submitted sitemaps contain the canonical URLs a site wants surfaced in Search.
The large site content audit segmentation matrix
Segment on several dimensions rather than searching for one magical score. The purpose is not to produce an impressive dashboard. It is to stop unlike pages from competing under an arbitrary standard.
- Page type: guide, news article, review, product, category, support document, archive, location page or generated landing page.
- Reader job and intent: learn, compare, choose, buy, troubleshoot, navigate or complete a task.
- Organic performance: strong, growing, declining, visible without clicks, or effectively absent.
- Topic cluster: the subject, entity and journey stage the page owns, including likely overlap with nearby URLs.
- Freshness: evergreen, periodically changing, event-bound, factually expired or uncertain.
- Business value: direct conversion, assisted conversion, revenue, retention, support deflection or strategic relevance.
- Authority and support: backlinks, internal prominence, expert contribution and evidence quality.
- Technical state: indexable, canonical, duplicate, redirected, broken, blocked, orphaned or parameterized.
- Differentiation risk: unique evidence and a clear reader job versus templated, derivative or interchangeable copy.
Template-level problems should be isolated early. If hundreds of URLs share thin introductory copy, missing specifications or broken canonical logic, auditing them individually wastes time. Diagnose the template first with a template quality audit for large sites, then inspect representative URLs and exceptions.
Use different decision questions for different page types
| Page type | Primary decision question | Useful evidence | Common mistake |
|---|---|---|---|
| Editorial guide | Does it still solve a distinct reader problem accurately and better than nearby pages? | Queries, trend, factual changes, conversions, links and overlap | Refreshing the date without improving the answer |
| Product page | Does it help a qualified visitor evaluate and buy this specific product? | Revenue, availability, specifications, returns, links and assisted conversions | Deleting it because search traffic is modest |
| Category or collection | Does it help users navigate and compare a meaningful product set? | Demand, inventory, filters, conversion rate and internal links | Treating it as a long-form article |
| Support documentation | Does it resolve a current customer task? | Support usage, product version, ticket patterns and completion signals | Judging it only by acquisition traffic |
| Tag or archive | Does it provide a useful browsing route distinct from search and category pages? | Internal use, overlap, indexation and crawl patterns | Leaving every automatically generated archive indexable |
| Faceted or filter URL | Does this combination represent stable demand and a useful landing experience? | Canonical state, inventory depth, demand and duplication | Sending it to editors before technical review |
| Review | Does it contain evidence, criteria and conclusions beyond product summaries? | Method, observations, comparisons, disclosures and reader fit | Scaling interchangeable reviews without real differentiation |
| Programmatic set | Does every generated page have distinct inputs, value and ownership? | Coverage quality, exceptions, duplication and maintenance process | Assuming scale itself creates useful coverage |
Segment first, then score comparable cohorts
Use a two-stage process. First, assign every URL to a page-type and purpose cohort. Second, score or classify it relative to pages with comparable jobs. A score can help order work, but it should not be allowed to make irreversible decisions automatically.
For example, editorial guides could receive separate ratings for continuing demand, trend, factual accuracy, differentiation, conversions, backlinks and overlap. Product pages may instead be judged on availability, revenue, specifications, user decision support and replacement status. Filter URLs need canonicalization, demand and inventory checks before normal editorial scoring is useful.
Avoid universal deletion thresholds such as “remove anything with no clicks in six months.” The appropriate observation window depends on seasonality, page type, sales cycle and business value. A page can also receive impressions without many clicks, indicating that it may warrant a title, positioning or intent review rather than deletion.
Topic overlap needs judgment as well. Similar keywords or overlapping search results are clues, not proof that two pages should merge. Compare their reader jobs, query-to-URL patterns, content evidence and intended journey stage. The framework in using SERP similarity to investigate cannibalization can help prevent premature consolidation.
Turn segments into action queues
Once URLs have meaningful cohorts, place them into operational queues. Each queue should have its own owner, evidence requirements and definition of done.
- Protect: high-value pages that are accurate and effective. Monitor them and avoid careless redesigns, URL changes or internal-link losses.
- Refresh: pages with a valid purpose but outdated facts, weakening performance, changing intent or poor conversion support.
- Expand or differentiate: pages with a worthwhile job but insufficient evidence, examples, specifications, analysis or first-hand inputs.
- Consolidate: materially overlapping pages where one stronger destination can satisfy the shared intent. Preserve valuable material and map redirects deliberately.
- Technical triage: canonical conflicts, blocked pages, redirect chains, indexable filters, broken URLs and template defects requiring technical ownership.
- Retire, redirect or noindex: obsolete or unhelpful inventory with no defensible standalone purpose. The choice depends on replacement relevance, links and user need.
- Quarantine: pages involving legal, medical, financial, reputational or unresolved data risks that need specialist review.
Consolidation deserves post-launch measurement rather than blind confidence. Record the affected URLs, queries, links, conversions and implementation date before the merge, then compare appropriate periods afterward. A dedicated content consolidation measurement plan makes the result easier to interpret.
Worked example: a mixed 20,000-URL site
Imagine an ecommerce and publishing site with 8,000 product URLs, 1,000 category and collection pages, 2,000 guides, 3,000 discontinued products, 4,000 filter combinations and 2,000 tags, archives and utility URLs. This is a hypothetical example, but it shows why one score would be absurd.
- Protect converting products and categories, including those with modest organic traffic but clear revenue or assisted value.
- Review older guides with continuing impressions but declining clicks. Check whether the result presentation, title, facts or answer no longer match the intended query.
- Group guides by topic and reader job. Investigate substantial overlap before merging, rather than consolidating merely because titles contain similar words.
- Separate discontinued products with backlinks, demand or viable replacements from those with no meaningful value. Redirect only where the destination genuinely serves the former user need.
- Send indexable filters, parameter combinations and canonical conflicts to technical triage before assigning editorial rewrites.
- Assess unused tags and archives as a cohort. Retain those that create valuable navigation; noindex, consolidate or retire those with no identifiable reader job.
- Sample scaled and AI-assisted sets for unsupported claims, repetitive structure, weak differentiation and unclear ownership before deciding whether the problem is isolated or systemic.
Crawl-budget work should not become a fashionable excuse for every cleanup project. Google describes crawl-budget optimization as advanced work mainly relevant to very large or frequently changing sites and sites showing substantial crawling or indexing symptoms. Investigate it when evidence supports the concern, not whenever a crawl discovers untidy URLs.
Do not create a “Helpful Content Update recovery” segment
Historical labels can distort current diagnosis. On March 5, 2024, Google announced that helpfulness assessment had become part of its core ranking systems rather than remaining tied to one standalone helpful-content system. Google later said on August 15, 2024 that the August core update aimed in part to better capture improvements sites had made.
That history does not give auditors a special recovery formula. Segment pages by reader value, differentiation, purpose, technical state and business role. Calling every decline a “helpful content” problem may cause teams to rewrite pages that actually suffer from demand shifts, duplication, weak internal architecture, SERP changes or commercial friction.
Measure outcomes without inventing causality
Capture a baseline for each action cohort: valid indexed pages, clicks, impressions, click-through rate, conversions, revenue, referring domains and crawl or canonical errors as applicable. Annotate implementation dates and compare equivalent periods where seasonality matters.
After changes, monitor both intended destinations and removed URLs. Improvement following an audit does not prove that one edit caused it. Competitor activity, demand, technical releases and ranking-system changes may occur at the same time. Report the result as an observed change, then test alternative explanations.
The operating rule for auditing 1,000 articles
Build segments before issuing editorial assignments. Audit one action cohort at a time, beginning with technically invalid URLs and high-value pages at risk, then move to refreshes, differentiation work and consolidation opportunities.
Most importantly, never hand a content team a generic mandate to “improve every low-traffic page.” Give them a page purpose, the evidence behind the diagnosis, the intended action and a measurable definition of done. That turns a large-site audit from spreadsheet theater into a workable quality-control system.
References
- Creating Helpful, Reliable, People-First Content | Google Search Central | Documentation | Google for Developers
- Creating Helpful, Reliable, People-First Content | Google Search Central | Documentation | Google for Developers
- Performance report (Search results): Dimensions and data groupings – Search Console Help
- Crawl Budget Management | Google Crawling Infrastructure | Crawling infrastructure | Google for Developers
- Build and Submit a Sitemap | Google Search Central | Documentation | Google for Developers
- What web creators should know about our March 2024 core update and new spam policies | Google Search Central Blog | Google for Developers
- What to know about our August 2024 core update | Google Search Central Blog | Google for Developers