How to Segment a Large Site Before Auditing Pages
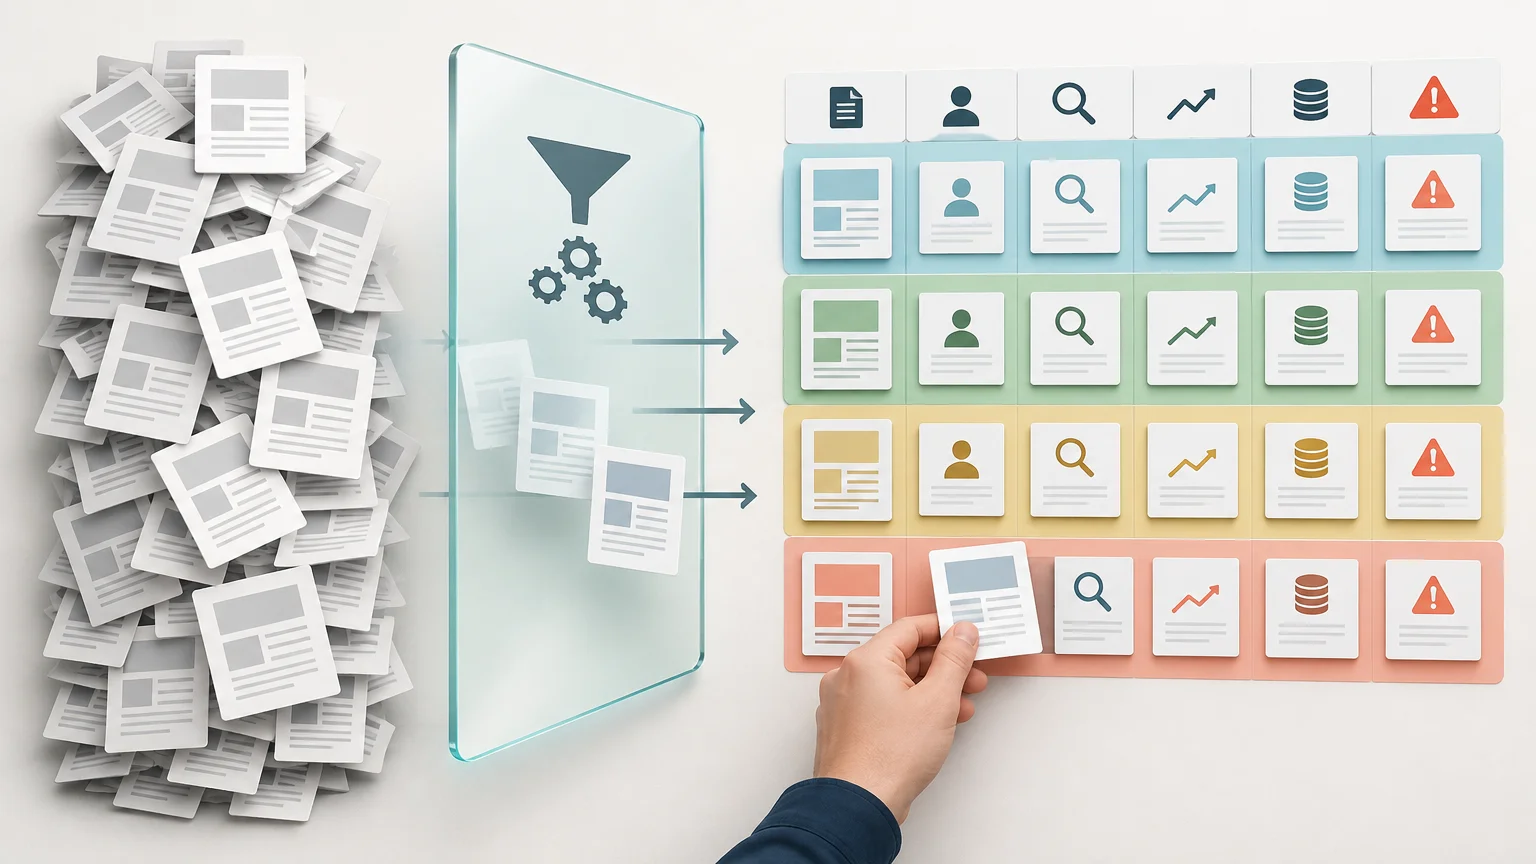
Do not begin a large-site content audit by sorting every URL from highest traffic to lowest and reviewing the rows in that order. First divide the inventory into groups whose pages have comparable jobs, templates, audiences, performance expectations and risks. Then evaluate each group using criteria appropriate to that group.
The useful unit is neither the entire site nor an isolated URL. It is the cohort: product pages serving the same kind of demand, editorial guides built from the same template, location pages with the same purpose, or articles in a similar stage of their lifecycle. Cohorts expose recurring problems without pretending every page in a directory deserves the same verdict.
A good segmentation model answers three questions before anyone starts scoring content: What is this page supposed to do? What evidence would show that it is doing that job? Which other pages are reasonable comparisons? If those answers are unclear, the audit will produce confident-looking spreadsheets and weak decisions.
Why a URL list is not yet an audit inventory
A crawl export gives you addresses, status codes, canonicals, titles and other machine-readable attributes. It does not give you a defensible content model. Two URLs can sit in the same folder while serving different audiences, and two pages on different subdomains can perform the same reader job.
This matters because Google says its ranking systems primarily operate at the page level, although some site-wide signals and classifiers are also used. A weak cohort should therefore prompt an investigation into shared templates, intent, sourcing or production practices. It is not proof that a directory has received a simple section-level penalty.
Segmentation makes page-level review more accurate while revealing repeated causes. If 80 buying guides share the same empty comparison table, that is a template problem expressed across individual pages. If only six guides are weak because their topics have no meaningful demand, the appropriate response may be page-specific rather than a template rebuild.
Build segments in layers, not with one master label
The common mistake is trying to assign every URL one permanent category such as “blog,” “product” or “poor performer.” Those labels mix page identity with audit findings. A product page can be valuable, non-indexable, recently published and technically broken at the same time.
Use several independent fields instead. Each field should describe one aspect of the page, remain understandable to reviewers and support an actual decision.
| Segmentation layer | Question it answers | Example values | How it changes the audit |
|---|---|---|---|
| Page type | What kind of asset is this? | Product, category, article, tool, location, support | Determines the baseline template and expected content elements |
| Reader job or intent | What is the visitor trying to accomplish? | Learn, compare, buy, troubleshoot, navigate | Prevents unlike pages from being judged by the same criteria |
| Lifecycle state | Where is the page in its useful life? | New, established, declining, seasonal, obsolete | Changes the time window and urgency of review |
| Search performance | How does it acquire and satisfy search demand? | Growing, stable, declining, unseen, query mismatch | Identifies patterns requiring deeper diagnosis |
| Business role | Why does the organization maintain it? | Revenue, lead generation, support, authority, compliance | Stops traffic from becoming the only measure of value |
| Technical state | Can search engines access and interpret it as intended? | Indexable, canonicalized, redirected, orphaned, blocked | Separates technical eligibility from content quality |
| Quality or risk flag | What concern requires human review? | Thin differentiation, stale facts, duplication, weak sourcing | Directs specialist attention without prejudging the final action |
These fields can be combined when prioritizing work, but do not concatenate every attribute into hundreds of microscopic segments. “Declining informational articles with weak sourcing” is usable. “Declining desktop informational articles published on Tuesdays with four images” probably is not.
Step 1: Create a canonical URL inventory
Start by combining URLs from sources that reveal different parts of the site: the current crawl, XML sitemaps, analytics landing pages, Search Console, CMS records and known backlink destinations. Preserve the source of discovery in separate columns.
Normalize obvious variants, but do not delete them silently. Parameters, trailing-slash versions, alternate protocols, pagination and duplicate canonicals may be evidence of an architecture problem. Record the preferred URL alongside discovered variants so the team can distinguish a content asset from the many addresses through which it is exposed.
Before content scoring, classify HTTP status, indexability, declared canonical, canonical target, robots directives, crawl depth and sitemap presence. A redirected URL does not need the same content review as its destination. A canonicalized duplicate may still require template or navigation work, but it should not be counted as an independent article needing a rewrite.
Google identifies faceted navigation, duplicate content, soft 404s, infinite URL spaces and low-quality pages as potential sources of unnecessary crawling. It also warns that making low-quality pages faster does not itself make them more desirable to crawl. Google’s crawling guidance is a useful reminder that crawl efficiency and content usefulness are connected but not interchangeable problems.
Step 2: Classify page type from purpose, not URL syntax
Directories and templates are helpful starting clues, not authoritative classifications. A URL under /blog/ might be a news post, evergreen guide, campaign landing page or thin support announcement. Detect the template automatically where possible, then validate what the page actually does.
Define page types narrowly enough to support different audit rules. An ecommerce site may need separate classes for product detail pages, product families, filtered listings, buying guides, inspiration content and customer support. A publisher may distinguish news, evergreen explainers, reviews, comparisons, data studies and reference pages.
Write a short inclusion rule for each type. For example: “A comparison page helps a reader choose among named alternatives and must explain meaningful differences.” That definition is more useful than “pages using template 14” because it establishes what reviewers should expect to find.
For page types driven by a common layout, run a separate template quality audit before assuming every weakness requires individual editing. Shared missing specifications, repetitive introductions or broken modules can make hundreds of pages look like isolated editorial failures.
Step 3: Add the reader job and demand model
Page type describes the format. Reader job describes why the page should exist. A guide may teach a process, define a term, compare methods or help someone recover from a specific failure. Those jobs require different evidence and should not compete by default.
Use query data, page copy, navigation context and conversion paths to assign a primary reader job. Add a secondary job only when it materially affects the review. If nobody can articulate the job without reciting a target keyword, flag the page for closer inspection.
This is where thin differentiation becomes visible. Twenty pages may have distinct keywords but answer essentially the same question. Conversely, two pages with overlapping queries may serve different stages of a task and deserve to remain separate. Search-result similarity can inform the analysis, but it should not replace page purpose, query-to-URL evidence or editorial judgment.
Google’s people-first content guidance asks whether a page offers original information, substantial value relative to other results, clear sourcing and evidence of expertise. It also asks whether content appears mass-produced or created mainly to attract search visits. Those questions are much more useful when applied within a coherent cohort than as a generic checkbox across an entire domain.
Step 4: Segment performance without letting traffic dictate quality
Add performance after identity and purpose. Otherwise, the audit quietly defines low traffic as low quality and high traffic as success. Both assumptions fail regularly.
Use several performance states rather than one arbitrary traffic threshold:
- Growing: impressions, clicks or valuable actions are rising across a meaningful comparison period.
- Stable: performance remains within an expected range for the page type and season.
- Declining: losses persist after accounting for seasonality, demand and site changes.
- Unseen: the page receives little or no measurable search visibility despite sufficient time and technical eligibility.
- Query mismatch: the page appears for searches that do not match its intended job, or multiple URLs repeatedly exchange visibility for the same query set.
- Non-search asset: the page primarily supports customers, campaigns, compliance or navigation and should not be judged as a search landing page.
Choose comparison windows that fit the cohort. Seasonal pages need year-over-year context. New pages need time to accumulate meaningful evidence. News and product-launch pages may have short demand cycles. An evergreen guide should not receive a deletion recommendation merely because its topic was quiet last month.
When investigating a sustained decline, Google recommends examining affected pages and query types, separating search types where relevant and avoiding dramatic conclusions from small movements. After a core update, it recommends waiting at least a full week after rollout completion before comparing periods.
Large sites should also account for extraction limits and aggregation. Search Console metrics can differ depending on whether data is grouped by property or page. The Search Analytics API is limited to 50,000 rows per day per search type, while bulk export to BigQuery provides ongoing URL-level data without that daily row limit, although anonymized queries remain excluded.
Step 5: Add business value and editorial risk
Search performance is evidence, not the company mission. Add fields for revenue contribution, assisted conversions, lead quality, customer support value, contractual obligations and strategic authority. Use ranges or controlled labels when exact attribution would imply more precision than the data supports.
Then add quality and risk flags. These should identify what needs investigation, not prescribe the outcome. Useful flags include unsupported claims, outdated facts, missing product details, near-duplicate copy, weak authorship signals, empty generated sections, intrusive monetization and mismatch between title and page purpose.
Turn the segments into an audit sampling plan
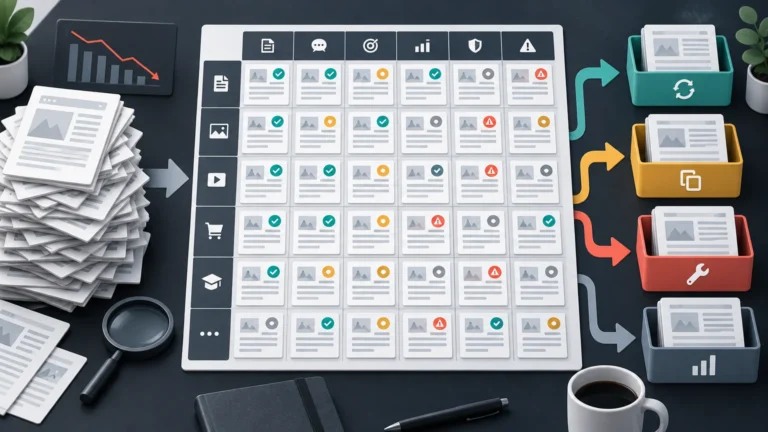
Once the fields are populated, create a matrix of meaningful cohorts. Start with high-volume or high-risk combinations such as declining comparison pages, indexable faceted pages, unseen evergreen articles and revenue-driving categories with thin supporting information.
Review a sample from each cohort before assigning bulk actions. Include strong, average and weak performers rather than inspecting only the bottom rows. The contrast helps identify whether a feature is actually associated with success or merely common across the template.
For an unseen-content cohort, use the more focused process for auditing old pages that have never ranked. Some will need stronger evidence or a better match to demand; others may overlap with established pages or have no defensible reader job.
Document the dominant pattern, exceptions and confidence level. If a sample reveals several unrelated failure modes, split the cohort and inspect again. If pages share a clear template defect, repair the template and validate the change on a controlled subset before rolling it across the inventory.
Do not jump from segmentation to mass deletion
Segmentation is valuable because it supports consistent decisions, but consistency can become recklessness at scale. A weak cohort may need rewriting, consolidation, deindexing, technical cleanup, repositioning or no action at all. Deletion should follow evidence that the pages cannot be salvaged and provide no other meaningful value; Google describes removal as a last resort rather than a standard response to a core update.
A published pruning case study reported removing or hiding 198 of 600 URLs that had generated about 3.1% of site clicks. The author later observed organic gains but also disclosed paid-search changes, content rewrites and Google updates as confounding factors. It is a useful content-pruning case study precisely because it does not prove that deletion alone caused the improvement.
When overlap is the problem, define the stronger destination and success measures before merging pages. The implementation should preserve useful material, map redirects deliberately and establish a measurement window. A separate content consolidation test is more defensible than treating every low-performing cohort as disposable.
The minimum viable segmentation schema
If the full model feels too heavy, begin with eight fields: preferred URL, indexability, page type, primary reader job, lifecycle state, performance state, business role and risk flag. Add owner, template and action fields once reviewers have validated the taxonomy.
Keep the vocabulary controlled. Publish definitions beside the spreadsheet or database, provide examples and record “unknown” rather than forcing uncertain classifications. After the first sample review, revise labels that produce disagreement or fail to change a decision.
The final output should not be a prettier URL export. It should be a map of comparable page populations, each with an explicit purpose, relevant evidence and a sensible review method. Build that map first. Then the page audit can answer the question that matters: whether each asset performs a worthwhile job, and whether the recurring problem belongs to the page, the template, the architecture or the publishing strategy.
Frequently Asked Questions
What is the best unit for auditing pages on a large site?
Use a cohort: pages with comparable jobs, templates, audiences, lifecycle stages or risks. It reveals recurring problems without pretending every URL deserves the same criteria or verdict.
Which fields should a basic segmentation schema include?
Start with preferred URL, indexability, page type, primary reader job, lifecycle state, performance state, business role and risk flag. Add ownership, template and proposed-action fields after validating the taxonomy.
Should page type be determined from the URL folder?
No. Directories and templates are useful clues, but classification should reflect what the page actually does. A URL under /blog/ could be news, an evergreen guide, a campaign page or a support notice.
Why should performance be added after page purpose?
Starting with traffic encourages the lazy assumption that low traffic means poor quality and high traffic means success. Define the asset and its reader job first, then interpret performance within that context.
How should seasonal and newly published pages be evaluated?
Use comparison windows appropriate to the cohort. Seasonal pages need year-over-year context, while new pages need enough time to accumulate meaningful evidence. A quiet month alone does not justify deleting an evergreen guide.
How should a large site handle Search Console data limits?
Account for grouping, extraction limits and excluded anonymized queries. The Search Analytics API is limited to 50,000 rows per day per search type, while bulk export to BigQuery provides ongoing URL-level data without that daily row limit.
Does a weak directory indicate a section-level Google penalty?
Not by itself. Google says its ranking systems primarily operate at the page level, while also using some site-wide signals and classifiers. A weak cohort should trigger investigation into shared templates, sourcing, intent or production practices.
Should low-performing cohorts be deleted in bulk?
No. A weak cohort may need rewriting, consolidation, deindexing, technical cleanup, repositioning or no action. Google describes removal as a last resort when content cannot be salvaged, not a routine response to a core update.
References
- Google Search's Core Updates | Google Search Central | Documentation | Google for Developers
- A Guide to Google Search Ranking Systems | Google Search Central | Documentation | Google for Developers
- Troubleshoot Google Search Crawling Errors | Google Search Central | Documentation | Google for Developers
- Creating Helpful, Reliable, People-First Content | Google Search Central | Documentation | Google for Developers
- Getting your performance data | Search Console API | Google for Developers
- Bulk data export: a new and powerful way to access your Search Console data | Google Search Central Blog | Google for Developers
- Content pruning case study: Cutting 33% of pages that drove just 3% of clicks